Where does a bioinformatician spend most of the day?
Data comes from the lab. The job is turning it into answers with computing, statistics and maths.
All the code, quizzes and links from the two sessions on bioinformatics and data science. Run the code, change it, break it, run it again.
No installation. You only need a browser and a Google account.
No Colab? Open a new notebook, then use the button.
dna = "ATGGTGCACCTGACTCCTGAGGAGAAG"   # start of the human beta-globin gene (HBB)

print("Length:", len(dna))
for base in "ACGT":
    print(base, dna.count(base))

def gc_content(seq):
    gc = seq.count("G") + seq.count("C")
    return gc / len(seq)

print("GC content:", round(gc_content(dna), 2))

bases = "TCAG"
amino = ("FFLLSSSSYY**CC*W"
         "LLLLPPPPHHQQRRRR"
         "IIIMTTTTNNKKSSRR"
         "VVVVAAAADDEEGGGG")
codons = [a + b + c for a in bases for b in bases for c in bases]
code = dict(zip(codons, amino))

def translate(seq):
    protein = ""
    for i in range(0, len(seq) - 2, 3):
        protein += code[seq[i:i + 3]]
    return protein

print(len(code), "codons")
print(translate(dna))

def mutate(seq, position, new_base):
    return seq[:position] + new_base + seq[position + 1:]

sickle = mutate(dna, 19, "T")

print(translate(dna), "healthy")
print(translate(sickle), "sickle cell")

# Try a synonymous mutation: change the third letter of codon 2 (GTG -> GTA)
silent = mutate(dna, 5, "A")
print(translate(silent), "same protein?", translate(silent) == translate(dna))

def needleman_wunsch(a, b, match=1, mismatch=-1, gap=-2):
    n, m = len(a), len(b)
    F = [[0] * (m + 1) for _ in range(n + 1)]
    for i in range(n + 1):
        F[i][0] = i * gap
    for j in range(m + 1):
        F[0][j] = j * gap
    for i in range(1, n + 1):
        for j in range(1, m + 1):
            s = match if a[i - 1] == b[j - 1] else mismatch
            F[i][j] = max(F[i - 1][j - 1] + s, F[i - 1][j] + gap, F[i][j - 1] + gap)
    # traceback from the bottom-right cell
    top, bottom, i, j = "", "", n, m
    while i > 0 or j > 0:
        s = match if i > 0 and j > 0 and a[i - 1] == b[j - 1] else mismatch
        if i > 0 and j > 0 and F[i][j] == F[i - 1][j - 1] + s:
            top, bottom, i, j = a[i - 1] + top, b[j - 1] + bottom, i - 1, j - 1
        elif i > 0 and F[i][j] == F[i - 1][j] + gap:
            top, bottom, i = a[i - 1] + top, "-" + bottom, i - 1
        else:
            top, bottom, j = "-" + top, b[j - 1] + bottom, j - 1
    return F, F[n][m], top, bottom

def show(a, b):
    F, score, top, bottom = needleman_wunsch(a, b)
    print("     " + "".join(f"{c:>4}" for c in "-" + b))
    for label, row in zip("-" + a, F):
        print(f"{label:>4} " + "".join(f"{v:>4}" for v in row))
    print("\nScore:", score)
    print(top)
    print(bottom)

show("GATC", "GAC")
print()
show("GAATTC", "GATTA")

import pandas as pd
from sklearn.tree import DecisionTreeClassifier, export_text

train = pd.DataFrame({
    "food":      ["Maize", "Maize", "Maize", "Maize", "Rice", "Rice", "Swordfish", "Swordfish", "Apple", "Apple", "Maize", "Rice"],
    "origin":    ["non-EU", "non-EU", "EU", "EU", "non-EU", "EU", "non-EU", "EU", "EU", "non-EU", "non-EU", "non-EU"],
    "season":    ["summer", "winter", "summer", "winter", "summer", "winter", "summer", "winter", "summer", "winter", "summer", "winter"],
    "retested":  ["yes", "yes", "no", "no", "no", "no", "yes", "yes", "no", "no", "yes", "no"],
    "non_compliant": ["yes", "yes", "no", "no", "no", "no", "yes", "yes", "no", "no", "yes", "no"],
})
test = pd.DataFrame({
    "food":   ["Maize", "Swordfish", "Rice", "Maize", "Apple", "Maize"],
    "origin": ["non-EU", "EU", "EU", "EU", "non-EU", "non-EU"],
    "season": ["summer", "summer", "summer", "summer", "summer", "winter"],
    "non_compliant": ["yes", "yes", "no", "yes", "no", "no"],
})
y = train["non_compliant"]

for cols in (["food", "origin", "season", "retested"], ["food", "origin", "season"]):
    X = pd.get_dummies(train[cols])
    model = DecisionTreeClassifier(random_state=0).fit(X, y)
    print("Columns:", cols)
    print(export_text(model, feature_names=list(X.columns)))

X_test = pd.get_dummies(test[cols]).reindex(columns=X.columns, fill_value=False)
test["prediction"] = model.predict(X_test)
print(test)
print("Correct:", (test["prediction"] == test["non_compliant"]).sum(), "out of", len(test))

probability = [0.92, 0.85, 0.78, 0.71, 0.66, 0.61, 0.55, 0.52, 0.47, 0.44,
               0.38, 0.35, 0.31, 0.27, 0.22, 0.18, 0.14, 0.11, 0.07, 0.04]
risky = [1, 1, 1, 0, 1, 0, 1, 0, 0, 1, 0, 0, 0, 1, 0, 0, 0, 0, 0, 0]
CHECK, MISSED = 200, 5000   # euro

for threshold in [0.3, 0.4, 0.5, 0.7]:
    checked = [p >= threshold for p in probability]
    tp = sum(c and r for c, r in zip(checked, risky))
    missed = sum(risky) - tp
    n_checks = sum(checked)
    cost = n_checks * CHECK + missed * MISSED
    print(f"threshold {threshold}: {n_checks:2} checks, recall {tp / sum(risky):.0%}, "
          f"precision {tp / n_checks:.0%}, missed {missed}, cost {cost} euro")

import sqlite3

db = sqlite3.connect(":memory:")   # a small database that lives only in memory
db.executescript("""
CREATE TABLE hospitals (id INTEGER PRIMARY KEY, name TEXT, region TEXT);
CREATE TABLE reports   (id INTEGER PRIMARY KEY, hospital_id INTEGER, area TEXT, signed INTEGER);
""")
db.executemany("INSERT INTO hospitals VALUES (?, ?, ?)",
               [(1, "Hospital A", "Emilia-Romagna"), (2, "Hospital B", "Puglia")])

# Made-up data. Hospital A: 100 reports, 90 signed. Hospital B: 900 reports, 450 signed.
reports = []
for i in range(100):
    reports.append((1, "Radiology" if i < 40 else "Lab", 1 if i < 90 else 0))
for i in range(900):
    reports.append((2, "Radiology" if i < 300 else "Lab", 1 if i < 450 else 0))
db.executemany("INSERT INTO reports (hospital_id, area, signed) VALUES (?, ?, ?)", reports)

query = """
SELECT h.name,
       COUNT(*)                                   AS reports,
       SUM(r.signed)                              AS signed,
       ROUND(100.0 * SUM(r.signed) / COUNT(*), 1) AS signed_pct
FROM reports r
JOIN hospitals h ON r.hospital_id = h.id
GROUP BY h.name;
"""
rows = db.execute(query).fetchall()
for row in rows:
    print(row)

# The trap: the average of the two percentages is not the share for the whole group
pcts = [row[3] for row in rows]
print("Average of the percentages:", sum(pcts) / len(pcts), "%")
total = db.execute("SELECT ROUND(100.0 * SUM(signed) / COUNT(*), 1) FROM reports").fetchone()[0]
print("Real share for the group:", total, "%")
Only what we did in class: the live demos and the challenges. Each block depends on the ones above it.
A DNA sequence is a string: Python can measure it, count letters and compute the GC content.
dna = "ATGGTGCACCTGACTCCTGAGGAGAAG"   # start of the human beta-globin gene (HBB)

print("Length:", len(dna))
for base in "ACGT":
    print(base, dna.count(base))

def gc_content(seq):
    gc = seq.count("G") + seq.count("C")
    return gc / len(seq)

print("GC content:", round(gc_content(dna), 2))The genetic code is a lookup table: 64 codons, 20 amino acids and 3 stop signals (*). Each line of amino is one block of the textbook table (first base T, C, A, G).
bases = "TCAG"
amino = ("FFLLSSSSYY**CC*W"
         "LLLLPPPPHHQQRRRR"
         "IIIMTTTTNNKKSSRR"
         "VVVVAAAADDEEGGGG")
codons = [a + b + c for a in bases for b in bases for c in bases]
code = dict(zip(codons, amino))

def translate(seq):
    protein = ""
    for i in range(0, len(seq) - 2, 3):
        protein += code[seq[i:i + 3]]
    return protein

print(len(code), "codons")
print(translate(dna))One letter changes, the protein changes. Codon 7 GAG becomes GTG: glutamic acid (E) becomes valine (V). This is the variant behind sickle cell disease.
def mutate(seq, position, new_base):
    return seq[:position] + new_base + seq[position + 1:]

sickle = mutate(dna, 19, "T")

print(translate(dna), "healthy")
print(translate(sickle), "sickle cell")

# Try a synonymous mutation: change the third letter of codon 2 (GTG -> GTA)
silent = mutate(dna, 5, "A")
print(translate(silent), "same protein?", translate(silent) == translate(dna))The grid from Challenge A, filled by the computer. Match +1, mismatch -1, gap -2. The function returns the grid, the best score and one best alignment.
def needleman_wunsch(a, b, match=1, mismatch=-1, gap=-2):
    n, m = len(a), len(b)
    F = [[0] * (m + 1) for _ in range(n + 1)]
    for i in range(n + 1):
        F[i][0] = i * gap
    for j in range(m + 1):
        F[0][j] = j * gap
    for i in range(1, n + 1):
        for j in range(1, m + 1):
            s = match if a[i - 1] == b[j - 1] else mismatch
            F[i][j] = max(F[i - 1][j - 1] + s, F[i - 1][j] + gap, F[i][j - 1] + gap)
    # traceback from the bottom-right cell
    top, bottom, i, j = "", "", n, m
    while i > 0 or j > 0:
        s = match if i > 0 and j > 0 and a[i - 1] == b[j - 1] else mismatch
        if i > 0 and j > 0 and F[i][j] == F[i - 1][j - 1] + s:
            top, bottom, i, j = a[i - 1] + top, b[j - 1] + bottom, i - 1, j - 1
        elif i > 0 and F[i][j] == F[i - 1][j] + gap:
            top, bottom, i = a[i - 1] + top, "-" + bottom, i - 1
        else:
            top, bottom, j = "-" + top, b[j - 1] + bottom, j - 1
    return F, F[n][m], top, bottom

def show(a, b):
    F, score, top, bottom = needleman_wunsch(a, b)
    print("     " + "".join(f"{c:>4}" for c in "-" + b))
    for label, row in zip("-" + a, F):
        print(f"{label:>4} " + "".join(f"{v:>4}" for v in row))
    print("\nScore:", score)
    print(top)
    print(bottom)

show("GATC", "GAC")
print()
show("GAATTC", "GATTA")The made-up data from Challenge C. With the column retested the model cheats (data leakage). Without it, it finds the rule on its own.
import pandas as pd
from sklearn.tree import DecisionTreeClassifier, export_text

train = pd.DataFrame({
    "food":      ["Maize", "Maize", "Maize", "Maize", "Rice", "Rice", "Swordfish", "Swordfish", "Apple", "Apple", "Maize", "Rice"],
    "origin":    ["non-EU", "non-EU", "EU", "EU", "non-EU", "EU", "non-EU", "EU", "EU", "non-EU", "non-EU", "non-EU"],
    "season":    ["summer", "winter", "summer", "winter", "summer", "winter", "summer", "winter", "summer", "winter", "summer", "winter"],
    "retested":  ["yes", "yes", "no", "no", "no", "no", "yes", "yes", "no", "no", "yes", "no"],
    "non_compliant": ["yes", "yes", "no", "no", "no", "no", "yes", "yes", "no", "no", "yes", "no"],
})
test = pd.DataFrame({
    "food":   ["Maize", "Swordfish", "Rice", "Maize", "Apple", "Maize"],
    "origin": ["non-EU", "EU", "EU", "EU", "non-EU", "non-EU"],
    "season": ["summer", "summer", "summer", "summer", "summer", "winter"],
    "non_compliant": ["yes", "yes", "no", "yes", "no", "no"],
})
y = train["non_compliant"]

for cols in (["food", "origin", "season", "retested"], ["food", "origin", "season"]):
    X = pd.get_dummies(train[cols])
    model = DecisionTreeClassifier(random_state=0).fit(X, y)
    print("Columns:", cols)
    print(export_text(model, feature_names=list(X.columns)))

X_test = pd.get_dummies(test[cols]).reindex(columns=X.columns, fill_value=False)
test["prediction"] = model.predict(X_test)
print(test)
print("Correct:", (test["prediction"] == test["non_compliant"]).sum(), "out of", len(test))The 20 batches from Challenge D. For each threshold we count checks, missed risky batches and total cost.
probability = [0.92, 0.85, 0.78, 0.71, 0.66, 0.61, 0.55, 0.52, 0.47, 0.44,
               0.38, 0.35, 0.31, 0.27, 0.22, 0.18, 0.14, 0.11, 0.07, 0.04]
risky = [1, 1, 1, 0, 1, 0, 1, 0, 0, 1, 0, 0, 0, 1, 0, 0, 0, 0, 0, 0]
CHECK, MISSED = 200, 5000   # euro

for threshold in [0.3, 0.4, 0.5, 0.7]:
    checked = [p >= threshold for p in probability]
    tp = sum(c and r for c, r in zip(checked, risky))
    missed = sum(risky) - tp
    n_checks = sum(checked)
    cost = n_checks * CHECK + missed * MISSED
    print(f"threshold {threshold}: {n_checks:2} checks, recall {tp / sum(risky):.0%}, "
f"precision {tp / n_checks:.0%}, missed {missed}, cost {cost} euro")The query from slide 36, on the same made-up data: hospital A signs 90 reports out of 100, hospital B 450 out of 900. Together, is it 70%? Python includes sqlite3, so it runs in Colab with nothing to install.
import sqlite3

db = sqlite3.connect(":memory:")   # a small database that lives only in memory
db.executescript("""
CREATE TABLE hospitals (id INTEGER PRIMARY KEY, name TEXT, region TEXT);
CREATE TABLE reports   (id INTEGER PRIMARY KEY, hospital_id INTEGER, area TEXT, signed INTEGER);
""")
db.executemany("INSERT INTO hospitals VALUES (?, ?, ?)",
               [(1, "Hospital A", "Emilia-Romagna"), (2, "Hospital B", "Puglia")])

# Made-up data. Hospital A: 100 reports, 90 signed. Hospital B: 900 reports, 450 signed.
reports = []
for i in range(100):
    reports.append((1, "Radiology" if i < 40 else "Lab", 1 if i < 90 else 0))
for i in range(900):
    reports.append((2, "Radiology" if i < 300 else "Lab", 1 if i < 450 else 0))
db.executemany("INSERT INTO reports (hospital_id, area, signed) VALUES (?, ?, ?)", reports)

query = """
SELECT h.name,
       COUNT(*)                                   AS reports,
       SUM(r.signed)                              AS signed,
       ROUND(100.0 * SUM(r.signed) / COUNT(*), 1) AS signed_pct
FROM reports r
JOIN hospitals h ON r.hospital_id = h.id
GROUP BY h.name;
"""
rows = db.execute(query).fetchall()
for row in rows:
    print(row)

# The trap: the average of the two percentages is not the share for the whole group
pcts = [row[3] for row in rows]
print("Average of the percentages:", sum(pcts) / len(pcts), "%")
total = db.execute("SELECT ROUND(100.0 * SUM(signed) / COUNT(*), 1) FROM reports").fetchone()[0]
print("Real share for the group:", total, "%")# A
def at_content(seq):
return (seq.count("A") + seq.count("T")) / len(seq)
print(round(gc_content(dna) + at_content(dna), 2))
# B
protein = translate("ATGAAATAGGGC")
print(protein, "first stop at position", protein.index("*"))
# C
for threshold in [0.3, 0.4, 0.5, 0.7]:
checked = [p >= threshold for p in probability]
missed = sum(r and not c for c, r in zip(checked, risky))
print(threshold, sum(checked) * 200 + missed * 500, "euro")
# D
for row in db.execute("""
SELECT r.area,
COUNT(*) AS reports,
ROUND(100.0 * SUM(r.signed) / COUNT(*), 1) AS signed_pct
FROM reports r
JOIN hospitals h ON r.hospital_id = h.id
WHERE h.region = 'Puglia'
GROUP BY r.area;"""):
print(row)Try them first. Solutions are at the bottom.
A. Write at_content(seq), the share of A and T. Check that gc_content(dna) + at_content(dna) is 1.
B. Find the position of the first stop codon (*) in translate("ATGAAATAGGGC").
C. Change the costs in section 6: if a missed batch costs only 500 euro, which threshold is cheapest?
D. In section 7, write a query for Puglia only: how many reports per area (Lab, Radiology), and what share is signed? Hint: add WHERE h.region = 'Puglia' and group by r.area.
The questions from the two sessions. Pick an answer to see why.
Data comes from the lab. The job is turning it into answers with computing, statistics and maths.
3.1 billion bases × 2 bits ÷ 8 is about 775 million bytes. Raw sequencer data is far bigger.
4 × 4 × 4 = 64. There are only 20 amino acids, so several codons mean the same one, and 3 mean stop.
BLAST only computes around short exact 'seeds'. It can miss weak similarities, but it answers in seconds.
Two Gs and two Cs: 4 out of 6.
That is the header. The sequence starts on the next line.
The model memorised the examples instead of learning a rule.
Recall looks only at the truly risky batches: 4 caught out of 5. Precision is 4 out of 10, i.e. 40%.
A false positive costs one extra test. A false negative can put a non-compliant product on the market.
The slides of both sessions and the notebooks used in class.
Five paths that connect subjects, starting from what we saw in the two sessions. Pick one and build it with your teachers.
Free, public tools used by researchers every day.
Tell me how it went. The form is anonymous and takes 2 minutes.
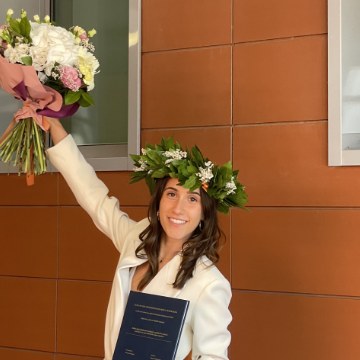
Martina Castellucci. Diploma here at Liceo Ferrari, then a BSc in Biotechnology and an MSc in Bioinformatics at the University of Bologna. My thesis internship was at Neotron Laboratories in Modena, on predicting food contamination risk. Since October 2026 I work as a Product Specialist at Onit in Cesena, on healthcare data warehouses and dashboards.
Pick your answer, then turn the screen to the stage.